Agent Landscape #1: The 5 Things Every Production Agent Needs
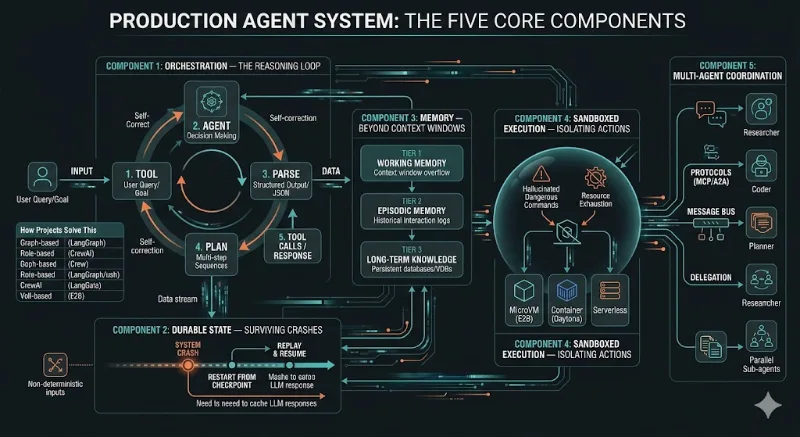
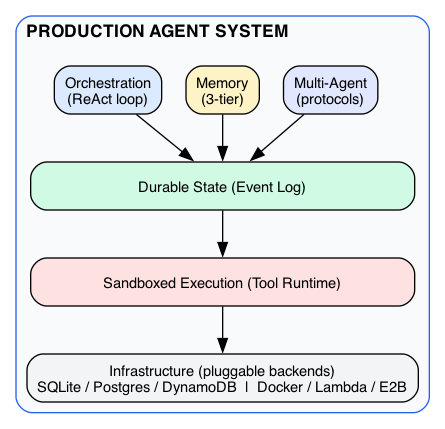
TLDR: Every production agent needs 5 components: orchestration (reasoning loop), durable state (survive crashes), memory (3-tier: working + long-term + session), sandboxed execution (isolated tool runtime), and multi-agent coordination (MCP/A2A/AG-UI). No single project covers all 5 — OpenClaw (378k), Hermes (190k), and AgentScope (26k) come closest at 4/5. The hard problems are distributed systems problems applied to a new domain.
The Problem
You can build a working AI agent in 50 lines of Python:
while True:
    response = llm.chat(messages, tools=tools)
    if response.tool_calls:
        for call in response.tool_calls:
            result = execute_tool(call)
            messages.append(result)
    else:
        break
This works in a demo. In production, it fails in five specific ways:
- The loop has no memory of itself. Restart the process and all progress is lost.
- The context window overflows. After 50 tool calls, the model forgets why it started.
- Tools run in the same process. A hallucinated
os.remove("/")executes with full permissions. - One agent can’t do everything. Complex tasks need specialized sub-agents that coordinate.
- The reasoning loop itself is fragile. No structured error handling, no retries, no multi-step planning.
Every team discovers these in production — usually in this order. After analyzing every relevant open-source project (totaling 3.0M+ GitHub stars across 11 categories), one pattern emerged: each project solves 1-2 of these problems excellently.
Component 1: Orchestration — The Reasoning Loop
The Problem
A raw LLM API call returns text. An agent needs to:
- Decide whether to call a tool or respond
- Parse tool arguments reliably (structured output, not regex)
- Handle tool failures (retry? skip? escalate?)
- Plan multi-step sequences (not just react to the last result)
- Know when to stop (avoid infinite loops)
Without orchestration, you get agents that hallucinate tool calls, loop forever, or crash on the first error.
What’s Actually Needed
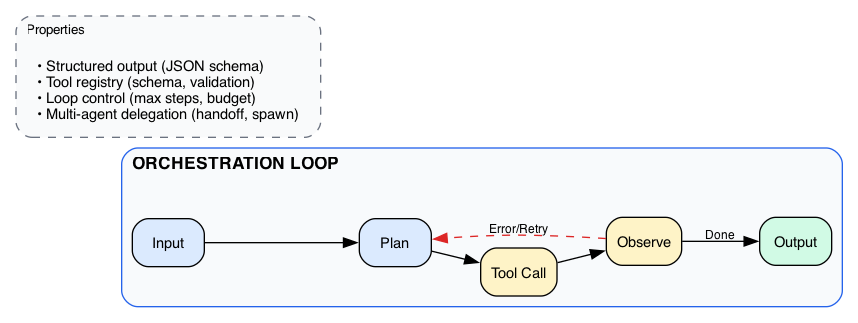
The key architectural decisions:
- How to represent control flow: Graph (LangGraph), roles (CrewAI), typed functions (PydanticAI), self-organizing (Hermes)
- How to enforce structured output: JSON schema (most), Pydantic models (PydanticAI), code-as-output (Smolagents)
- How to handle multi-agent: Shared memory (dangerous), message passing (AutoGen), delegation (DeerFlow/Hermes), handoff (Swarm)
How Projects Solve This
| Approach | Projects | Pattern | Trade-off |
|---|---|---|---|
| Graph-based | LangGraph (34k) | Nodes = functions, edges = control flow. State propagates through graph. | Most expressive, steepest learning curve |
| Role-based | CrewAI (53k), MetaGPT (68k) | Agents have roles/goals. Crews collaborate on tasks. | Intuitive but shallow — hard to control fine-grained logic |
| Type-safe | PydanticAI (17k) | Typed inputs/outputs, dependency injection for tools | Best DX, single-agent only |
| Self-improving | Hermes (190k), OpenClaw (378k) | Agent extracts skills from experience, improves over time | Most powerful long-term, hardest to debug/audit |
| Code-as-action | Smolagents (28k) | LLM writes Python as its “tool”, executed in sandbox | Maximally flexible, harder to constrain |
| Visual | Dify (145k), n8n (192k) | Drag-and-drop workflow builder | Fastest to prototype, limited for complex logic |
The gap: Every framework handles the “happy path” well. The difference shows in error recovery, loop control, and what happens when the LLM returns something unexpected. Most frameworks offer some error handling (PydanticAI retries on validation failure, CrewAI retries/delegates failed tasks, Smolagents feeds execution errors back to the LLM) — but LangGraph and AgentScope provide the most granular control: node-level error routing, configurable retry policies with backoff, and fallback edges.
Component 2: Durable State — Surviving Crashes
The Problem
Your agent has been working for 30 minutes. It’s made 47 tool calls, gathered data from 12 APIs, and is about to execute the final step. Then:
- The process OOMs
- A deploy restarts the container
- The network partitions
All work is lost. The user starts over. Or worse: the agent partially executed something (sent half an email, created 3 of 5 resources) and now the system is in an inconsistent state.
What’s Actually Needed
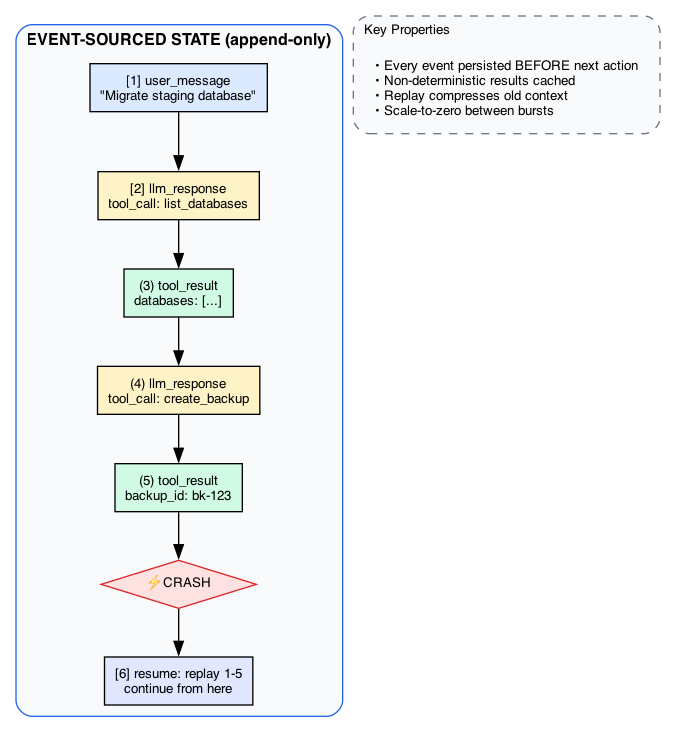
The critical subtlety for agents: LLM calls are non-deterministic. Traditional event sourcing replays by re-executing. Agent event sourcing must cache the LLM response — replaying the same prompt might produce a different plan.
How Projects Solve This
| Approach | Projects | Pattern | Trade-off |
|---|---|---|---|
| Full event sourcing | Temporal (21k) | Every decision recorded in event history. Replay on crash. | Gold standard durability, but requires Temporal Server + determinism constraint awkward for LLM calls |
| Step-level caching | Inngest (5k) | Each step.run() cached individually. Crash → restart from last cached step. | Serverless-friendly, simpler, but coarser granularity |
| Checkpoint | LangGraph (34k) | Periodic state snapshots. Resume from last checkpoint. | Simple, but loses inter-checkpoint state |
| Session-based | AgentScope (26k), OpenClaw (378k) | Session state persisted to DB. Resume by reloading session. | Practical, but no event-level granularity |
| None | CrewAI, PydanticAI, Agno, most frameworks | No persistence. Crash = start over. | Fine for short tasks, fatal for anything >5 minutes |
The gap: Agent-native event sourcing — durability that understands LLM calls are non-deterministic, context windows need compression on replay, and tool calls have schemas that can be validated on resume — remains an open problem.
Component 3: Memory — Beyond Context Window Overflow
The Problem
Context windows are finite. GPT-4o: 128k tokens. Claude: 200k tokens. Sounds like a lot — until your agent:
- Has a 10-turn conversation with tool results (easily 50k tokens)
- Needs to reference facts from 3 sessions ago
- Must remember user preferences across weeks of interaction
- Accumulates knowledge that should persist forever
When the window fills, the model either truncates (loses critical early context), summarizes (loses detail), or fails. Without memory management, agents degrade predictably: they forget their own instructions, repeat failed approaches, and lose user trust.
What’s Actually Needed
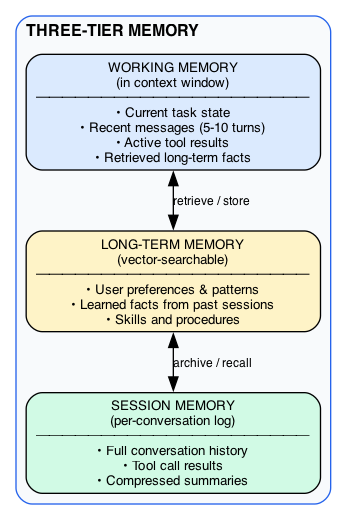
The key question: who manages memory? Two schools:
- Passive: The system automatically manages memory (truncate, summarize, embed). Simple but loses nuance.
- Agent-managed: The agent explicitly reads/writes/forgets memory as tool calls. More powerful but adds complexity to every interaction.
How Projects Solve This
| Approach | Projects | Pattern | Trade-off |
|---|---|---|---|
| Agent-managed (explicit) | Letta/MemGPT (23k) | Agent calls write_memory(), search_memory(), forget() as tools. Sleep-time consolidation. | Most sophisticated, but requires running Letta server |
| Self-improving memory | Hermes (190k), OpenClaw (378k) | Agent extracts “skills” from experience, stores in skill library, retrieves on similar tasks | Agents get better over time, but hard to audit what was learned |
| Bolt-on layer | Mem0 (58k) | m.add(fact), m.search(query) — framework-agnostic memory API | Easiest integration (3 lines), but external to reasoning loop |
| Checkpoint-based | LangGraph (34k) | Graph state persisted at checkpoints. Working memory only. | Simple, no long-term memory |
| Vector DB (raw) | Chroma (27k), Qdrant, LanceDB | Store embeddings, answer similarity queries | Plumbing, not solution — no memory lifecycle management |
The gap: No project cleanly separates the three tiers while letting the agent control all of them. Letta comes closest but requires buying into their platform. Mem0 solves storage but not working-memory management.
Component 4: Sandboxed Execution — Isolating Dangerous Actions
The Problem
Agents call tools. Tools execute real actions: run code, call APIs, modify databases, send emails. The failure modes:
- Hallucinated dangerous commands:
rm -rf /,DROP TABLE users,kubectl delete namespace production - Data exfiltration: Agent sends sensitive data to an external endpoint
- Resource exhaustion: Infinite loop burns $10k in compute before anyone notices
- Privilege escalation: Tool inherits the agent’s full permissions instead of scoped access
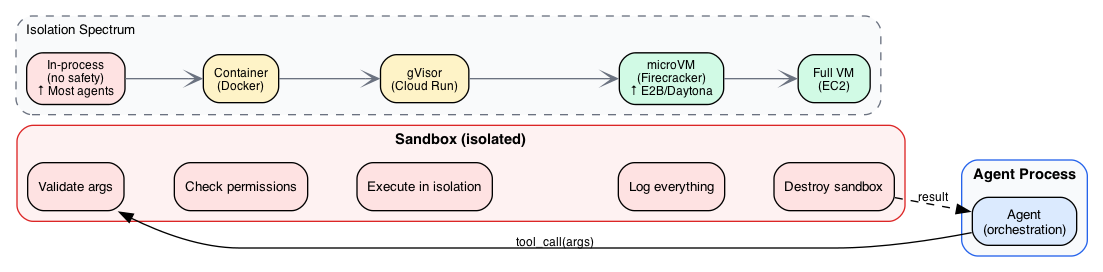
Most agent frameworks run tools in the same process as the agent — same permissions, same network access, same trust boundary. A hallucinated action executes with full authority.
What’s Actually Needed
How Projects Solve This
| Approach | Projects | Pattern | Trade-off |
|---|---|---|---|
| MicroVM sandbox | E2B (12k) | Firecracker microVM per execution. Own filesystem, network, process space. ~150ms boot. | Strongest isolation, managed-only, cost per hour |
| Container sandbox | Daytona (73k) | Container with snapshot/restore. <90ms boot. MCP-native. | Fastest, self-hostable, slightly weaker isolation than VM |
| Docker per-call | AgentScope (26k), OpenClaw (378k) | Fresh container per tool execution with scoped env vars | Self-hostable, familiar, slower cold start (1-5s) |
| Serverless function | Modal, Lambda, Fly.io | Decorated functions run in cloud isolation | Pay-per-second, GPU access (Modal), vendor lock-in |
| Code sandbox only | Smolagents (28k) | Python code executed in restricted interpreter | Lightweight but only covers code, not API calls |
| None | LangGraph, CrewAI, PydanticAI, most frameworks | Tools run in-process, same permissions as agent | Zero latency, zero safety |
The gap: Sandboxing projects don’t integrate with agent frameworks. Framework projects don’t provide sandboxing. You always glue them together yourself — and the integration surface (credential passing, result serialization, timeout handling) is where bugs hide.
Component 5: Multi-Agent Coordination — Agents Talking to Everything
The Problem
A single agent hits limits:
- Context window: One agent can’t hold a 200-page codebase + conversation + tool results
- Specialization: A research agent needs different tools and prompts than a coding agent
- Parallelism: Sequential tool calls are slow; parallel sub-agents are fast
- Cost: Routing simple queries to GPT-4 wastes money; a triage agent can delegate to cheaper models
But coordination introduces new failures:
- How do agents discover each other’s capabilities?
- How do you prevent infinite delegation loops?
- How do you share context without shared mutable state?
- Who handles failures in sub-agents?
What’s Actually Needed
How Projects Solve This
| Approach | Projects | Pattern | Trade-off |
|---|---|---|---|
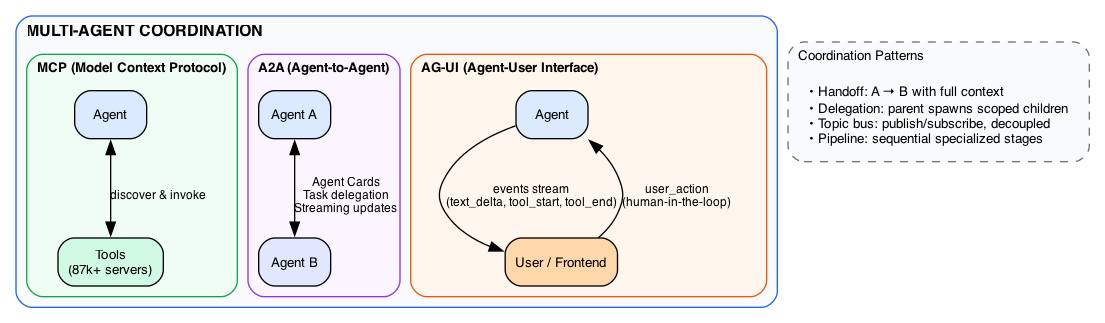
| Protocol-based (MCP) | Claude Code (130k), Cursor, Zed | Standard tool interface — any MCP server works with any MCP client | Universal but no auth/billing standard yet |
| Protocol-based (A2A) | Google ADK (20k), BeeAI | Agent Cards for discovery, task delegation with lifecycle | Cross-framework but still maturing |
| Event bus | AutoGen (59k) | Agents publish/subscribe to topics via gRPC | True distributed, but complex ops |
| Sub-agent delegation | DeerFlow (70k), Hermes (190k) | Parent spawns children with scoped context | Simple, but single-framework only |
| Handoff | Swarm (20k), OpenAI Agents SDK (27k) | Agent transfers conversation control to specialist | Low overhead, but limited to sequential delegation |
| Multi-agent routing | OpenClaw (378k) | Isolated agents per channel/account, gateway routes | Good for personal multi-agent, not for inter-org |
| Role-based crew | CrewAI (53k) | Define roles + goals, framework coordinates | Intuitive but shallow coordination |
The gap: Protocols define how agents communicate, but not how to handle failures, budgets, or trust between agents from different organizations. The “service mesh for agents” — discovery, load balancing, circuit breakers, mutual auth — doesn’t exist yet.
The Integration Map
Who Covers What
No project spans all 5. Here’s the honest coverage map:
| Project | Stars | Orchestration | Durability | Memory | Sandboxing | Coordination |
|---|---|---|---|---|---|---|
| OpenClaw | 378k | Yes | Session | Skills | Docker | Multi-agent routing |
| Hermes | 190k | Yes | Skills | Self-improving | 6 backends | Subagents |
| AgentScope | 26k | Yes | Session | Basic | Docker/E2B | Pipeline + MCP + A2A |
| LangGraph | 34k | Yes | Checkpoint | - | - | Graph-based |
| Dify | 145k | Yes | DB | RAG | Code sandbox | Workflows |
| CrewAI | 53k | Yes | - | - | - | Roles |
| Temporal | 21k | - | Full event sourcing | - | - | Child workflows |
| Letta | 23k | Basic | - | Full 3-tier | - | - |
| E2B | 12k | - | - | - | Full VM isolation | - |
| Daytona | 73k | - | Snapshot | - | Container + MCP | - |
The closest to “complete”:
- OpenClaw (378k) — covers 4/5 for personal use, but not enterprise multi-tenant
- AgentScope (26k) — covers 4/5 with K8s deployment, but Alibaba ecosystem defaults
- Hermes (190k) — covers 4/5 with self-improvement, but pre-1.0 APIs
All three still lack full event-sourced durability.
The Full Landscape at a Glance
| Category | Top projects (by stars) | Combined stars |
|---|---|---|
| Agent Frameworks | OpenClaw, AutoGPT, Hermes, DeerFlow, MetaGPT, AutoGen, CrewAI, LangGraph, Swarm | ~1.0M |
| LLM Toolkits | LangChain, LlamaIndex, DSPy, Haystack | ~250k |
| Visual / Low-Code | Dify, n8n, Langflow, Flowise | ~540k |
| Coding Agents | Claude Code, Gemini CLI, OpenHands, Open Interpreter, Aider | ~450k |
| Web/Tools | Firecrawl, Browser Use, Crawl4AI, Composio, Skyvern | ~350k |
| Memory | Mem0, Letta | ~80k |
| Sandboxing | Daytona, E2B | ~85k |
| Protocols | MCP servers, A2A, AG-UI | ~125k |
| Durability | Prefect, Temporal, Inngest | ~48k |
| Platform SDKs | Vercel AI, Semantic Kernel, AWS Strands, Cloudflare, Google ADK | ~84k |
| Observability | Langfuse, LangSmith, Arize Phoenix, AgentOps | ~45k |
Total landscape: 60+ projects, 3.0M+ stars, 11 categories.
What This Means for Builders
If you’re evaluating frameworks: Ask which of the 5 components they cover. Most cover 1-2. The “Who Covers What” table above is your starting point.
If you’re building agents today: Pick orchestration first (Hermes for self-improving, LangGraph for flexible, AgentScope for all-in-one). Then add durability and sandboxing as first infrastructure investments. Accept 3-4 project integrations minimum.
If you’re building agent infrastructure: The opportunity is a unified platform that co-designs all 5 layers — with pluggable backends for laptop, Docker, Kubernetes, and serverless. This is the “Kubernetes for agents” opportunity.
The Deeper Pattern
The hard problems in agent engineering are distributed systems problems applied to a new domain:
| Agent Problem | Distributed Systems Equivalent |
|---|---|
| Survive crashes | Event sourcing, write-ahead log |
| Memory management | Tiered storage, caching, eviction |
| Tool isolation | Container orchestration, sandboxing |
| Agent coordination | Service mesh, message bus, discovery |
| Non-deterministic replay | Idempotency, cached side effects |
We’ve solved all of these before. The industry just hasn’t applied them to agents in a unified way yet.
Next: Agent Landscape #2: Orchestration — Pick Your Reasoning Loop