Agent Landscape #2: Orchestration — Pick Your Reasoning Loop
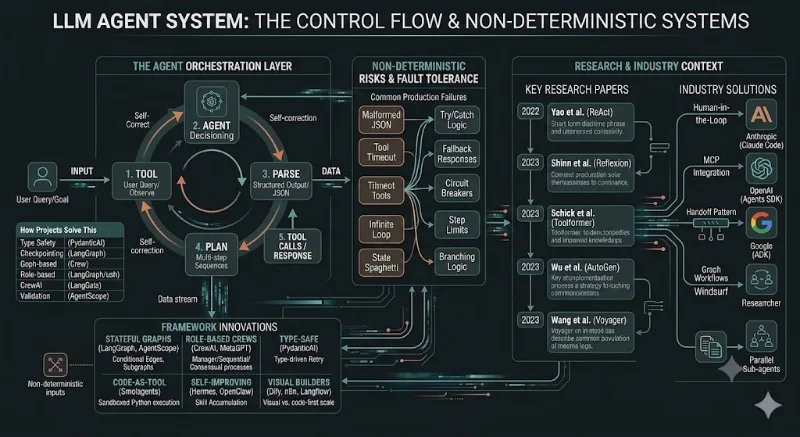
Which framework should you pick? It depends on what breaks first.
TLDR: Pick LangGraph (34k) for complex branching logic, CrewAI (53k stars) for fast prototyping, PydanticAI (17k) for type-safe single-agent, AgentScope (26k) for batteries-included. Hermes (190k) and OpenClaw (378k) add self-improvement. Visual builders (n8n 192k, Langflow 150k, Dify 145k) are how most teams actually start. The real differentiation isn’t the happy path — it’s error recovery, loop control, and whether the agent gets better over time.
The Problem
Your agent works perfectly in a demo: call a tool, get a result, respond. Then production happens:
- The LLM returns malformed JSON for the tool call → crash
- The tool times out → agent doesn’t know whether it succeeded or failed
- The LLM calls the same tool 50 times in a loop → infinite cost
- You need two agents to collaborate → how do they share state?
- The task requires 12 steps with branching logic → your
while Trueloop becomes spaghetti
The fundamental problem is control flow for non-deterministic systems. Traditional programming has if/else/try/catch. Agent orchestration needs the same — but the “program” is an LLM whose outputs are probabilistic, whose reasoning can loop, and whose tool calls have real-world side effects.
Research & Industry Context
Key Papers
ReAct (Yao et al., 2022) — established the think → act → observe pattern that almost every framework implements. Showed that interleaving reasoning traces with tool use outperforms either alone.
Reflexion (Shinn et al., 2023) — agents that reflect on failures and adjust strategy. Key insight: single-loop ReAct fails on complex tasks; adding a self-critique step dramatically improves multi-step success rates.
Toolformer (Schick et al., 2023) — LLMs that learn when and how to call tools. Demonstrated that tool selection is itself a learned capability, not just a prompt engineering problem.
LATS (Zhou et al., 2023) — Language Agent Tree Search. Combines Monte Carlo tree search with LLM agents for planning. Treats the action space as a tree and uses rollbacks on bad paths.
AutoGen (Wu et al., 2023, Microsoft) — formalized the multi-agent conversation pattern. Showed that specialized agents collaborating via message passing outperform monolithic agents on complex tasks.
Voyager (Wang et al., 2023) — self-improving agent in Minecraft. Key innovation: skill library that accumulates reusable procedures. Directly influenced Hermes and OpenClaw’s skill registries.
How Industry Solves This
Anthropic (Claude Code): ReAct loop with streaming, human-in-the-loop approval gates at destructive actions, MCP for tool integration. Persistent context across turns via conversation compaction. No framework — custom implementation optimized for coding tasks.
OpenAI (Swarm → Agents SDK): Handoff pattern — lightweight agent delegation without shared state. Each agent is a function that decides to respond or hand off. Designed for low-overhead multi-agent without the complexity of message buses.
Google (Gemini CLI / ADK): Graph-based workflows (similar to LangGraph) with A2A protocol for inter-agent communication. Agent Cards for capability discovery.
Cursor/Windsurf: Agentic IDE editing. The orchestration is deeply integrated with the IDE’s AST understanding — the agent reasons about code structure, not just text. Multi-file context management is the key differentiator.
Common production patterns across all:
- Structured output enforcement (JSON schema, not free-text parsing)
- Budget/step limits (prevent runaway loops)
- Human-in-the-loop at irreversible actions
- Streaming intermediate results (user sees progress)
- Graceful degradation (if tool fails, agent can still reason about the failure)
Open Source Solutions
LangGraph — 34k stars
What it is: Graph-based agent orchestration (from the LangChain team, but a separate project). Agents are stateful graphs — nodes are functions, edges define control flow.
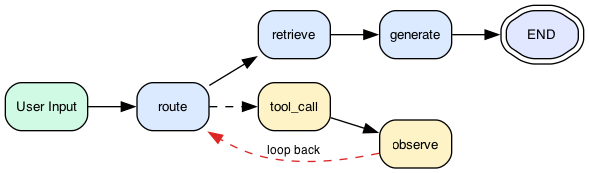
Architecture decisions:
- State is a typed dictionary that propagates through the graph
- Conditional edges enable branching (if/else in agent logic)
- Checkpointing at graph nodes (resume from last completed node)
- Subgraphs for encapsulation (nest one agent inside another)
Strengths:
- Most expressive orchestration model — any agent pattern is representable
- Checkpoint-based persistence — survive restarts
- Massive ecosystem (thousands of integrations)
- Streaming and human-in-the-loop built in
Limitations:
- No compute management — “bring your own everything” for infrastructure
- Checkpoints lose inter-checkpoint state (crash between checkpoints = lost work)
- Graph model has a learning curve — simple ReAct feels over-engineered
- No tool sandboxing — tools run in the same process
When to use: Complex agent patterns with branching logic. Your team can handle infrastructure complexity.
CrewAI — 53k stars
What it is: Role-based multi-agent framework. Agents have roles, goals, and backstories. They form “crews” that collaborate.
Crew(
  agents=[Researcher(role="...", goal="..."), Writer(role="...", goal="...")],
  tasks=[research_task, writing_task],
  process=Process.sequential
)
Architecture decisions:
- Agents defined by role + goal + backstory (natural language config)
- Processes: sequential, hierarchical (manager delegates), or consensual
- Tool sharing — agents can share tools or have exclusive access
- Delegation — agents can delegate subtasks to each other
Strengths:
- Lowest barrier to entry — multi-agent crew in 10 lines
- Intuitive mental model (roles = how people think about teams)
- Pre-integrated tools (Gmail, Slack, HubSpot)
Limitations:
- Shallow abstraction — fine-grained control is hard
- No event sourcing, no crash recovery
- Not for long-running tasks
When to use: Prototyping. Multi-agent tasks that complete in seconds/minutes.
PydanticAI — 17k stars
What it is: Type-safe agent framework. Structured inputs/outputs guaranteed by validation.
agent = Agent(model, result_type=MyPydanticModel, tools=[...])
result = agent.run_sync("query")  # typed, validated
Architecture decisions:
- Pydantic models define both input and output schemas
- Dependency injection for tool context (database connections, API clients)
- Retry logic with type-driven validation (model retries if output doesn’t validate)
- Model-agnostic — swap providers without changing agent code
Strengths:
- Type safety at definition time
- Structured outputs guaranteed by validation
- Clean dependency injection for tools
- Excellent DX for Pydantic-familiar teams
Limitations:
- Single-agent, single-turn focused
- No persistence, event log, or crash recovery
- No multi-agent coordination
When to use: Individual agent interactions that need reliable structured output. A building block for larger systems.
AgentScope (Alibaba) — 26k stars
What it is: The most complete all-in-one framework. Orchestration + K8s deployment + observability + sandboxing in one package.
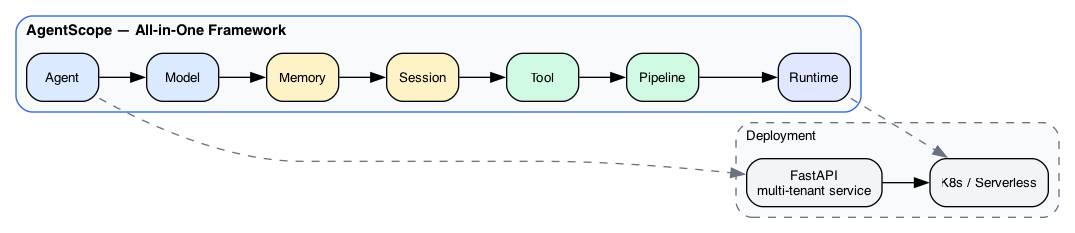
Architecture decisions:
- Agent abstraction wraps: model + memory + session + tools
- Pipeline orchestration (sequential, parallel, conditional)
- MCP + A2A protocol support (interop with external agents)
- OpenTelemetry middleware for distributed tracing
- Docker/E2B workspace for sandboxed tool execution
- Kubernetes deployment with scaling policies
Strengths:
- Most “batteries-included” — MCP + A2A + Docker/E2B + OpenTelemetry
- Deploy locally, serverless, or on Kubernetes
- FastAPI multi-tenant agent service with Web UI
Limitations:
- Alibaba ecosystem defaults (DashScope, TableStore)
- Large surface area
- Not serverless-native (agents are long-running processes)
When to use: You want everything in one package. You need MCP + A2A + K8s + observability without gluing 5 projects.
The Self-Improving Angle
OpenClaw — 378k stars
What it is: Local-first personal AI assistant. Runs on your devices, connects to messaging platforms you already use (WhatsApp, Telegram, Slack, Discord, Signal, iMessage). The largest agent project by stars.
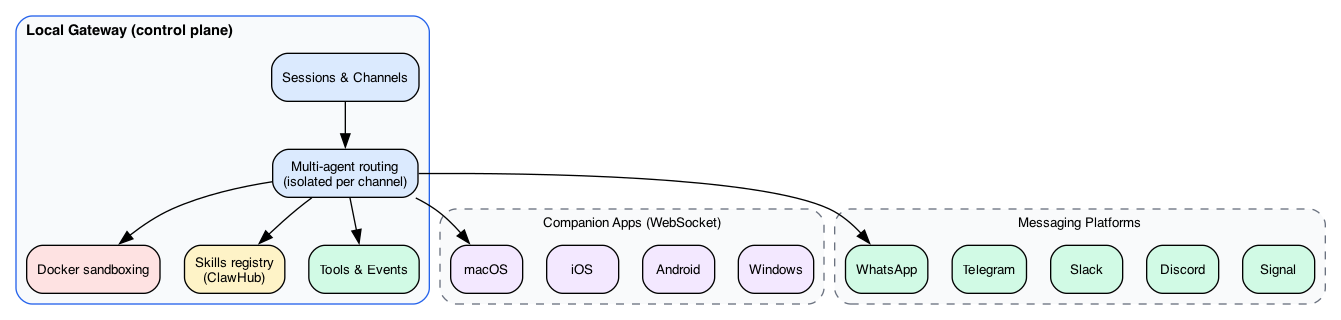
Architecture decisions:
- Gateway as single control plane (all tools, events, sessions flow through it)
- Multi-agent routing — different agents handle different channels/accounts
- Skills registry (ClawHub) — community-contributed reusable capabilities
- DM pairing for security (unknown senders can’t interact without pairing code)
Strengths:
- Local-first — runs on your own devices, data stays with you
- Multi-platform messaging out of the box (7+ platforms)
- Docker-based sandboxing built in
- Voice wake/talk mode, Live Canvas visual workspace
- Cron jobs, webhooks, skills registry
- MIT licensed, backed by OpenAI, GitHub, NVIDIA, Vercel
Limitations:
- Personal assistant focus — not designed for enterprise multi-tenant
- Node.js/TypeScript only
- Local-first means you manage your own infra
Key contribution: Proved that local-first + multi-platform + sandboxing is what users actually want.
Hermes Agent (NousResearch) — 190k stars
Core innovation: agents that learn from experience.
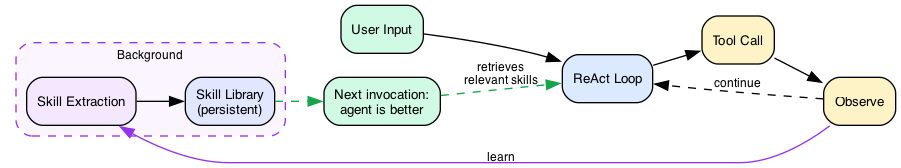
Architecture decisions:
- Skill extraction runs in background (doesn’t block the agent loop)
- Skills are versioned and searchable (agent retrieves relevant skills per task)
- Self-improving via Voyager-style skill accumulation
- 6 terminal backends — same agent code runs locally, Docker, SSH, Modal, Daytona
Why 190k stars: An agent that remembers and grows is fundamentally different from one that starts fresh every session. This is the pattern Voyager (2023) established in research; Hermes brought it to general-purpose agents.
Strengths:
- Self-improving loop — autonomously creates and refines skills
- Multi-platform messaging (Telegram, Discord, Slack, WhatsApp)
- MCP integration
Limitations:
- Pre-1.0 (APIs evolving rapidly)
- Personal-agent focus — not for enterprise multi-tenant
- Self-improvement loop can be opaque
Visual / Low-Code Agent Builders
A massive adjacent category — not traditional frameworks, but how most teams actually start building agents:
| Platform | Stars | What it is | Best for |
|---|---|---|---|
| Dify | 145k | Open-source LLM app platform with visual workflow editor, RAG, agent mode | Teams that want GUI-first agent building with one-click deploy |
| n8n | 192k | Fair-code workflow automation with native AI capabilities, self-hostable | Connecting agents to 400+ integrations without code |
| Langflow | 150k | Visual agent and workflow builder (DataStax) | Prototyping agent flows visually, then exporting code |
| Flowise | 53k | Drag-and-drop AI agent builder | Non-developers building simple agent workflows |
Why include these: They’re how most teams prototype before committing to a code-first framework. The visual builders collectively (540k stars) dwarf the code-first frameworks. n8n alone (192k) outweighs LangGraph + CrewAI + PydanticAI + AgentScope combined. The trade-off: speed to prototype vs. flexibility in production.
Notable Patterns
| Framework | Stars | Key Pattern | Research Origin |
|---|---|---|---|
| LangChain | 138k | LLM application toolkit (chains, retrieval, prompts) | Foundation layer many frameworks build on |
| AutoGen (Microsoft) | 59k | Event-driven agent chat via topic bus | AutoGen paper (2023) — multi-agent conversation |
| DeerFlow (ByteDance) | 70k | Sub-agent spawning with scoped contexts | Hierarchical task decomposition |
| MetaGPT | 68k | Org structure as agent architecture (roles + SOPs) | “Software company” metaphor for coordination |
| Smolagents (HuggingFace) | 28k | Code-as-tool (LLM writes Python, executes in sandbox) | Toolformer lineage — code as universal tool |
| Agno | 40k | 5-line agent prototyping | Minimal ReAct implementation |
| Swarm (OpenAI) | 20k | Lightweight multi-agent handoffs | Influence on OpenAI Agents SDK handoff pattern |
| Qwen-Agent (Alibaba) | 5k | Framework for Qwen models with tool use + RAG | Qwen ecosystem |
| ChatDev | 25k | Virtual software company (like MetaGPT) | Multi-agent code generation via SOP |
| RAGFlow | 30k | RAG engine with deep document understanding | Advanced chunking + retrieval |
| Kotaemon | 18k | RAG-based document QA with citations | Citation-grounded generation |
Coding Agents: What Production Looks Like
These aren’t frameworks — they’re finished products showing the target architecture:
| Agent | Stars / Status | Architecture Pattern |
|---|---|---|
| Claude Code (Anthropic) | 130k | ReAct + MCP + human-in-the-loop + conversation compaction |
| Gemini CLI (Google) | 105k | Graph workflows + A2A protocol |
| OpenHands | 76k | Docker sandboxed agent with browser + terminal + code editing |
| Open Interpreter | 60k | Natural language → system commands (files, browser, terminal) |
| Cursor (Composer) | Closed-source | AST-aware agentic editing + multi-file context |
| Windsurf | Closed-source | Full IDE with agentic flows + cascading context |
| Manus | Closed-source | General-purpose autonomous agent with planning |
| Aider | 30k | Git-aware pair programming — edit/test/commit loop |
| Continue | 25k | Open-source IDE extension with agent mode |
| GPT Researcher | 20k | Multi-source research → structured long-form reports |
Common production patterns across all:
- Streaming intermediate output (user never stares at a spinner)
- Human-in-the-loop at destructive/irreversible actions
- Context management (compaction, sliding window, relevance filtering)
- Sandboxed execution (code runs in containers, not in-process)
- Progressive disclosure (show summary, expand on request)
The Full Comparison
Code-First Frameworks
| Framework | Stars | Multi-agent | Persistence | Sandboxing | Self-improving |
|---|---|---|---|---|---|
| OpenClaw | 378k | Multi-agent routing | Sessions | Docker | Skills registry |
| AutoGPT | 185k | - | Basic | - | - |
| Hermes | 190k | Subagents | Skills | 6 backends | Yes |
| LangChain | 138k | - | - | - | - |
| DeerFlow | 70k | Sub-agents | Via LangGraph | - | - |
| MetaGPT | 68k | Roles+SOPs | Basic | - | - |
| AutoGen | 59k | Chat bus | - | - | - |
| CrewAI | 53k | Roles | Basic | - | - |
| Agno | 40k | Basic | - | - | - |
| LangGraph | 34k | Graph | Checkpoint | - | - |
| Smolagents | 28k | - | - | Code only | - |
| AgentScope | 26k | Pipeline | Session | Docker/E2B | - |
| ChatDev | 25k | Roles | Basic | - | - |
| PydanticAI | 17k | - | - | - | - |
Visual / Low-Code Builders
| Platform | Stars | Multi-agent | Persistence | Sandboxing | Self-improving |
|---|---|---|---|---|---|
| Dify | 145k | Workflows | Yes (DB) | Code sandbox | - |
| n8n | 192k | Workflows | Yes (DB) | - | - |
| Langflow | 150k | Workflows | Basic | - | - |
| Flowise | 53k | Chains | Basic | - | - |
Coding Agents (Applications)
| Agent | Stars | Sandboxing | Persistence | MCP |
|---|---|---|---|---|
| Claude Code | 130k | Yes | Yes | Yes |
| Gemini CLI | 105k | Yes | - | - |
| OpenHands | 76k | Yes (Docker) | Yes | - |
| Open Interpreter | 60k | Optional | - | - |
| Aider | 30k | - | Git-based | - |
| Continue | 25k | - | - | - |
| GPT Researcher | 20k | - | - | - |
Key Takeaway
The orchestration layer is the most crowded category — but the real differentiation isn’t in the happy-path loop. It’s in:
- Error recovery: What happens when a tool fails? (Most: crash. LangGraph: conditional edge. AgentScope: retry policy.)
- Loop control: How do you prevent infinite reasoning? (Step limits, budget caps, convergence detection.)
- Self-improvement: Does the agent get better over time? (Only Hermes and OpenClaw.)
- Production infra: How does it deploy, scale, observe? (Only AgentScope ships this.)
The next post examines the second component — what happens when your agent can’t survive a restart.
Previous: Agent Landscape #1: The 5 Things Every Production Agent Needs Next: Agent Landscape #3: Durability — Why Your Agent Can’t Survive a Restart