Embedding Pipeline
Chunking strategies, embedding model selection, batch GPU inference, incremental index updates — from raw documents to searchable vectors.
The embedding pipeline transforms raw documents into searchable vectors — the foundation of every RAG system. Get chunking wrong and retrieval fails regardless of how good your LLM is. Get indexing wrong and latency kills the user experience.
1. Pipeline Overview
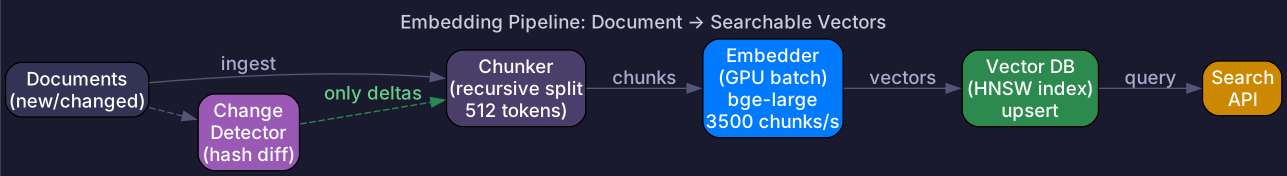
Documents → Chunk → Embed (GPU batch) → Index (vector DB) → Serve queries
    ↑                                          ↑
    └── Incremental update (detect changes) ───┘
Each stage has its own tradeoffs. Let’s walk through them.
2. Chunking Strategies
Chunking determines what each vector represents. Too large and the vector is vague; too small and it lacks context.
Fixed-Size Chunking
Split text into fixed token counts with overlap:
def fixed_size_chunk(text: str, chunk_size=512, overlap=64):
    """Split text into overlapping fixed-size chunks."""
    tokens = tokenizer.encode(text)
    chunks = []
    for i in range(0, len(tokens), chunk_size - overlap):
        chunk_tokens = tokens[i : i + chunk_size]
        chunks.append(tokenizer.decode(chunk_tokens))
return chunks| Parameter | Typical range | Effect |
|---|---|---|
chunk_size | 256-1024 tokens | Larger = more context per chunk, vaguer embedding |
overlap | 10-20% of chunk_size | Ensures sentences at boundaries aren’t lost |
Pros: Simple, predictable chunk count.
Cons: Splits mid-sentence, mid-paragraph — breaks semantic coherence.
Semantic Chunking
Split on natural boundaries (paragraphs, sections, sentences):
def semantic_chunk(text: str, max_tokens=512):
    """Split on paragraph boundaries, merge small paragraphs."""
    paragraphs = text.split("\n\n")
    chunks, current = [], ""

    for para in paragraphs:
        if token_count(current + para) > max_tokens:
            if current:
                chunks.append(current.strip())
            current = para
        else:
            current += "\n\n" + para

    if current:
        chunks.append(current.strip())
return chunksPros: Each chunk is a coherent semantic unit.
Cons: Variable chunk sizes — some may be very short (poor embeddings) or very long (exceeds model limit).
Recursive Chunking
Split hierarchically: try paragraphs first, then sentences, then fixed-size:
def recursive_chunk(text: str, max_tokens=512, separators=["\n\n", "\n", ". ", " "]):
    """Recursively split using natural boundaries."""
    if token_count(text) <= max_tokens:
        return [text]

    for sep in separators:
        parts = text.split(sep)
        if len(parts) > 1:
            chunks = []
            current = ""
            for part in parts:
                if token_count(current + sep + part) > max_tokens:
                    if current:
                        chunks.append(current)
                    current = part
                else:
                    current = current + sep + part if current else part
            if current:
                chunks.append(current)

            # Recursively split any still-too-large chunks
            result = []
            for chunk in chunks:
                result.extend(recursive_chunk(chunk, max_tokens, separators[1:]))
            return result

    # Last resort: hard split by tokens
    return fixed_size_chunk(text, max_tokens)
This is what LangChain’s RecursiveCharacterTextSplitter implements. It’s the most common production approach.
Which Chunking Strategy?
| Strategy | Quality | Simplicity | Best for |
|---|---|---|---|
| Fixed-size | Medium | High | Uniform documents (chat logs, code) |
| Semantic (paragraph) | High | Medium | Articles, documentation |
| Recursive | High | Medium | Mixed content |
| Document-level | Variable | High | Short documents (<512 tokens) |
3. Embedding Model Selection
| Model | Dimensions | MTEB score | Speed (tokens/s on A100) | Size |
|---|---|---|---|---|
all-MiniLM-L6-v2 | 384 | 56.3 | 14,000 | 80 MB |
bge-base-en-v1.5 | 768 | 63.6 | 8,000 | 440 MB |
e5-large-v2 | 1024 | 65.2 | 4,000 | 1.3 GB |
bge-large-en-v1.5 | 1024 | 64.2 | 3,500 | 1.3 GB |
gte-Qwen2-7B | 3584 | 72.1 | 800 | 14 GB |
Cohere embed-v3 | 1024 | 67.0 | — (API) | — |
OpenAI text-embedding-3-large | 3072 | 64.6 | — (API) | — |
Selection criteria:
- Quality: MTEB retrieval sub-scores (not overall, which includes classification)
- Latency: Must embed queries in <10ms for interactive RAG
- Cost: Self-hosted (GPU amortization) vs API ($0.02-0.13 per 1M tokens)
- Dimension: Higher dimensions = more storage but potentially better retrieval
Rule of thumb: Start with bge-base or e5-large for self-hosted. Use API embeddings only if you can tolerate the latency and cost.
4. Batch Embedding on GPU
Embedding at scale means processing millions of documents. GPU batch inference is essential:
from sentence_transformers import SentenceTransformer
import torch

model = SentenceTransformer("BAAI/bge-large-en-v1.5", device="cuda")

def batch_embed(chunks: list[str], batch_size=256) -> np.ndarray:
    """Embed chunks in GPU batches."""
    all_embeddings = []

    for i in range(0, len(chunks), batch_size):
        batch = chunks[i : i + batch_size]
        with torch.no_grad():
            embeddings = model.encode(
                batch,
                batch_size=batch_size,
                show_progress_bar=False,
                normalize_embeddings=True,  # L2 normalize for cosine similarity
            )
        all_embeddings.append(embeddings)

    return np.vstack(all_embeddings)

# Performance: bge-large on A100
# Batch size 256: ~3,500 chunks/sec (512 tokens each)
# 1M documents × 5 chunks each = 5M chunks → ~24 minutes on 1 A100
Throughput optimization
| Technique | Impact |
|---|---|
| Larger batch size (up to GPU memory) | 2-4× throughput |
| FP16 inference | 1.5-2× throughput, no quality loss |
| Sequence padding optimization | 20-30% throughput gain on variable-length input |
| Multi-GPU data parallel | Linear scaling |
# Variable-length padding optimization: sort by length, pad within batch
def sorted_batch_embed(chunks, batch_size=256):
    """Sort by length to minimize padding waste."""
    indexed = [(i, c) for i, c in enumerate(chunks)]
    indexed.sort(key=lambda x: len(x[1]))

    embeddings = [None] * len(chunks)
    for i in range(0, len(indexed), batch_size):
        batch_indices = [idx for idx, _ in indexed[i : i + batch_size]]
        batch_texts = [text for _, text in indexed[i : i + batch_size]]
        batch_embeds = model.encode(batch_texts, normalize_embeddings=True)
        for idx, emb in zip(batch_indices, batch_embeds):
            embeddings[idx] = emb

    return np.array(embeddings)
5. Incremental Updates
Re-embedding everything when a few documents change is wasteful. Track what changed:
class IncrementalEmbeddingPipeline:
    def __init__(self, vector_db, embedder, chunk_store):
        self.vector_db = vector_db
        self.embedder = embedder
        self.chunk_store = chunk_store  # stores doc_id → chunk hashes

    def update(self, documents: list[Document]):
        """Process only new or changed documents."""
        to_embed, to_delete = [], []

        for doc in documents:
            new_chunks = chunk(doc.content)
            new_hashes = [hash(c) for c in new_chunks]
            old_hashes = self.chunk_store.get(doc.id, [])

            if new_hashes == old_hashes:
                continue  # Document unchanged

            # Delete old chunks from vector DB
            to_delete.extend(self.chunk_store.get_chunk_ids(doc.id))

            # Embed new chunks
            for chunk_text, chunk_hash in zip(new_chunks, new_hashes):
                to_embed.append({
                    "doc_id": doc.id,
                    "text": chunk_text,
                    "hash": chunk_hash,
                })

            # Update chunk store
            self.chunk_store.set(doc.id, new_hashes)

        # Batch operations
        if to_delete:
            self.vector_db.delete(to_delete)
        if to_embed:
            vectors = self.embedder.encode([c["text"] for c in to_embed])
            self.vector_db.upsert(vectors, metadata=to_embed)

        return {"deleted": len(to_delete), "embedded": len(to_embed)}
Update Strategies
| Strategy | When to use | Latency |
|---|---|---|
| Real-time (on document change) | Low volume (<100 docs/min) | Seconds |
| Micro-batch (every 5 minutes) | Medium volume | Minutes |
| Daily rebuild | Large corpus, infrequent changes | Hours |
| Hybrid (real-time for new + daily for rebuild) | Production | Seconds for new, hours for reindex |
6. Metadata and Hybrid Search
Vectors alone aren’t enough. Store metadata alongside embeddings for filtered search:
# Insert with metadata
vector_db.insert(
    vectors=embeddings,
    metadata=[
        {
            "doc_id": "doc_123",
            "chunk_index": 0,
            "source": "engineering_docs",
            "date": "2024-01-15",
            "author": "alice",
            "section": "API Reference",
            "token_count": 487,
        }
        for chunk in chunks
    ]
)

# Filtered search: only search engineering docs from 2024
results = vector_db.search(
    vector=query_embedding,
    filter={"source": "engineering_docs", "date": {"$gte": "2024-01-01"}},
    top_k=20,
)
Hybrid Search (Vector + Keyword)
Combine dense vector search with sparse BM25 for best recall:
# Reciprocal Rank Fusion (RRF)
def hybrid_search(query, vector_db, bm25_index, top_k=10, alpha=0.7):
    """Combine vector and keyword search results."""
    vector_results = vector_db.search(embed(query), top_k=top_k * 2)
    keyword_results = bm25_index.search(query, top_k=top_k * 2)

    # RRF scoring
    scores = defaultdict(float)
    for rank, result in enumerate(vector_results):
        scores[result.id] += alpha / (60 + rank)       # vector weight
    for rank, result in enumerate(keyword_results):
        scores[result.id] += (1 - alpha) / (60 + rank)  # keyword weight

    # Sort by combined score
    ranked = sorted(scores.items(), key=lambda x: -x[1])
    return ranked[:top_k]
Hybrid search typically improves recall by 5-15% over vector-only, especially for exact term matching (product names, error codes).
Self-Check
- Compare fixed-size, semantic, and recursive chunking tradeoffs
- Select an embedding model given quality, latency, and cost constraints
- Calculate embedding throughput for a million-document corpus
- Design an incremental update pipeline that avoids re-embedding unchanged documents
- Implement hybrid search using Reciprocal Rank Fusion
References
- MTEB: Massive Text Embedding Benchmark
- BGE Embedding Models
- Reciprocal Rank Fusion (Cormack et al., 2009)
- For vector database internals, see Index Structures and System Architecture