Streaming Datasets
Mosaic StreamingDataset, WebDataset, HuggingFace streaming — reading from cloud storage without downloading entire datasets.
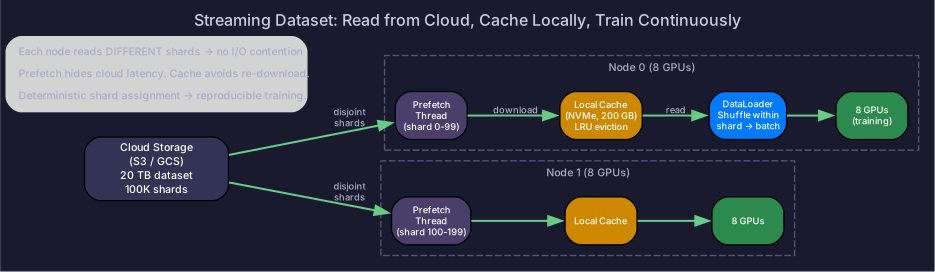
At pre-training scale, datasets are too large to fit on local disk. Streaming datasets read data directly from cloud storage (S3, GCS) — no full download needed, with built-in shuffling and multi-node coordination.
1. Why Streaming
| Approach | Local disk required | Startup time | Multi-node | Cloud-native |
|---|---|---|---|---|
| Download then train | Full dataset (10-50 TB) | Hours-days | Each node downloads | ❌ |
| Streaming | Cache only (100 GB) | Seconds | Built-in sharding | ✅ |
For a 15T token dataset at ~20 TB: downloading to each node wastes storage and delays training start. Streaming reads on-demand.
2. Mosaic StreamingDataset (MDS)
from streaming import StreamingDataset, StreamingDataLoader

# Data stored as MDS shards on S3
dataset = StreamingDataset(
    remote='s3://my-bucket/training-data/',
    local='/tmp/cache/',           # local cache for speed
    shuffle=True,
    shuffle_block_size=1 << 18,    # 256K samples per shuffle block
    batch_size=32,
)

loader = StreamingDataLoader(
    dataset,
    batch_size=32,
    num_workers=8,
)
Key Features
| Feature | How it works |
|---|---|
| Shard-based | Data split into fixed-size shards (64-256 MB each) |
| Deterministic shuffle | Same seed → same order across restarts (reproducibility) |
| Multi-node coordination | Each node gets disjoint shards (no duplicate reads) |
| Resumable | Track which shards consumed — resume after crash |
| Local cache | Downloaded shards cached locally; evicted when cache full |
Writing MDS Format
from streaming import MDSWriter

with MDSWriter(
    out='s3://my-bucket/training-data/',
    columns={'tokens': 'ndarray:int32', 'labels': 'ndarray:int32'},
    compression='zstd',
    size_limit=256 * 1024 * 1024,  # 256 MB per shard
) as writer:
    for sample in tokenized_dataset:
        writer.write(sample)
3. WebDataset
Tar-based format — each shard is a .tar file containing samples:
import webdataset as wds

dataset = wds.WebDataset(
    "s3://bucket/shards/shard-{000000..009999}.tar",
    shardshuffle=True,
).decode("pil").to_tuple("jpg", "cls")

loader = wds.WebLoader(dataset, batch_size=64, num_workers=8)
Best for: Vision datasets (image + label per sample). Each tar contains ~1000 samples. Simple format, works with standard tools.
4. HuggingFace Streaming
from datasets import load_dataset

dataset = load_dataset(
    "allenai/c4",
    split="train",
    streaming=True,  # don't download, stream!
)

for example in dataset:
    tokens = tokenizer(example["text"])
# process...Pros: Simplest API, huge hub of datasets. Cons: Less control over shuffling, no multi-node coordination (must implement manually), slower than MDS/WebDataset for large-scale training.
5. Comparison
| Feature | MDS (Mosaic) | WebDataset | HF Streaming |
|---|---|---|---|
| Format | Custom binary shards | Tar archives | Arrow/Parquet |
| Shuffle quality | Excellent (block shuffle) | Good (shard shuffle) | Limited |
| Multi-node | Built-in | Manual | Manual |
| Resume/checkpoint | Built-in | Manual | Manual |
| Compression | zstd, snappy | gzip, none | gzip |
| Best for | LLM pre-training | Vision training | Quick experiments |
| Throughput | Highest | High | Moderate |
For production pre-training: MDS or WebDataset. For research/prototyping: HF streaming.
6. Cloud Storage Bandwidth
| Storage | Read bandwidth | Latency | Cost |
|---|---|---|---|
| Local NVMe | 3-7 GB/s | ~10 μs | Included |
| S3 (single stream) | 100-200 MB/s | ~50 ms | $0.09/GB |
| S3 (parallel, 100 streams) | 10-20 GB/s | ~50 ms | Same |
| GCS | Similar to S3 | ~30 ms | $0.12/GB |
Key: Cloud storage has high throughput but high latency. Streaming datasets use prefetching + local caching to hide this latency.
For data loading at larger scale (thousands of workers), see Data Loading at Scale.
Self-Check
- Compare download-then-train vs streaming for a 20 TB dataset
- Set up Mosaic StreamingDataset with S3 and local cache
- Explain shard-based streaming: how shuffling and multi-node work
- Choose between MDS, WebDataset, and HF streaming for a given use case
- Calculate S3 bandwidth with parallel streams