Data Collection
Common Crawl processing, domain-specific scraping, licensing and compliance — where training data comes from and how to get it legally.
Training data is the foundation of every model. The quality, diversity, and legality of your data determine what the model can do — and what it can’t. This chapter covers where to get data, how to process it at scale, and how to stay legal.
1. The Data Landscape
| Source | Scale | Quality | Cost | Legal risk |
|---|---|---|---|---|
| Common Crawl | 250B+ pages | Low (raw web) | Free (processing cost) | Moderate (copyright) |
| Curated datasets (Wikipedia, StackOverflow, arXiv) | 10M-100M docs | High | Free-low | Low (open license) |
| Licensed datasets (news, books, academic) | Varies | High | $$$$ | Low (explicit license) |
| Domain-specific scraping | Custom | Variable | Medium (infra) | High (terms of service) |
| Synthetic data (model-generated) | Unlimited | Variable | Compute cost | Low (you own it) |
| User data (production logs, feedback) | Custom | High (real distribution) | Free | Moderate (privacy) |
The Data Mix for Modern LLMs
| Domain | Typical share | Why included |
|---|---|---|
| Web text (Common Crawl) | 60-70% | Broad world knowledge |
| Code (GitHub, StackOverflow) | 10-15% | Reasoning, code generation |
| Academic (arXiv, papers) | 5-10% | Scientific knowledge |
| Books | 5-10% | Long-form reasoning, style |
| Math | 3-5% | Mathematical reasoning |
| Curated Q&A | 2-5% | Instruction following |
2. Common Crawl Processing
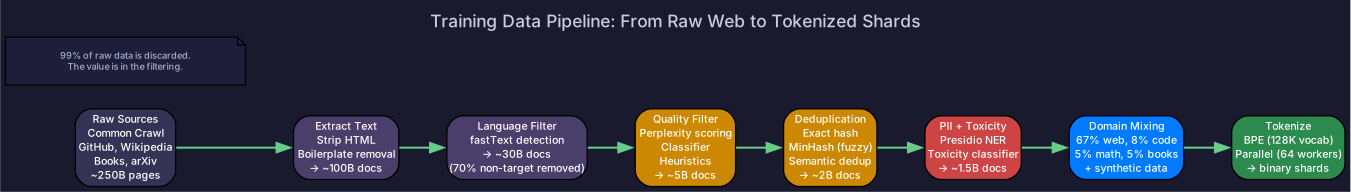
Common Crawl is the backbone of most pre-training datasets — petabytes of raw web text, freely available.
The Pipeline
Common Crawl WARC files (petabytes, raw HTML)
  → Extract text (strip HTML, boilerplate removal)
  → Language detection (fastText, CLD3)
  → Quality filtering (perplexity, classifier)
  → Deduplication (MinHash, exact match)
  → PII removal (regex + NER)
  → Toxicity filtering
  → Domain classification
  → Output: cleaned text corpus
Scale
| Stage | Input | Output | Reduction |
|---|---|---|---|
| Raw Common Crawl | 250B pages | — | — |
| After text extraction | ~100B documents | 60% removed (images, nav, etc.) | |
| After language filter (English) | ~30B documents | 70% non-English | |
| After quality filter | ~5B documents | 83% low quality | |
| After dedup | ~2B documents | 60% duplicates | |
| Final clean corpus | ~1-2B documents | 99% of raw data removed |
Key insight: You throw away 99% of Common Crawl. The value is in the filtering, not the collection.
3. Domain-Specific Collection
Code
# GitHub scraping (respect rate limits and licenses)
# Typical filters:
# - Stars > 10 (quality signal)
# - License: permissive (MIT, Apache, BSD)
# - Language: Python, JavaScript, C++, etc.
# - File size: < 1MB (skip generated/minified)
# - Dedup: exact file hash + near-dedup across repos
Academic Papers
- arXiv: Bulk download available (LaTeX source → extract text)
- Semantic Scholar: API for structured paper data
- PubMed: Biomedical papers (PubMed Central open access)
Structured Data
- Wikipedia: Dump available, well-structured, multilingual
- StackOverflow: Data dump, Q&A format with quality signals (votes)
- Wikidata: Knowledge graph for factual grounding
4. Licensing and Compliance
| License type | Can train on? | Can distribute model? | Examples |
|---|---|---|---|
| Public domain | ✅ | ✅ | Wikipedia, US government docs |
| CC-BY | ✅ | ✅ (with attribution) | Many academic papers |
| CC-BY-SA | ✅ | ⚠️ (share-alike may apply) | Some Wikipedia content |
| CC-BY-NC | ⚠️ (non-commercial only) | ❌ for commercial models | Some datasets |
| No license / © All rights reserved | ❌ (legally risky) | ❌ | Most web content |
| Terms of Service prohibit | ❌ | ❌ | Many news sites |
The Legal Landscape (2024-2025)
- Fair use (US): Argued by OpenAI, Google — training on copyrighted data may be fair use. Unsettled law.
- EU AI Act: Requires transparency about training data sources.
- Opt-out mechanisms: robots.txt, AI-specific opt-out headers becoming standard.
Practical advice: Document everything (sources, licenses, collection dates). Use permissively-licensed data where possible. Implement opt-out mechanisms.
For how to clean and filter collected data, see Cleaning & Filtering.
Self-Check
- Name the major data sources for LLM pre-training and their tradeoffs
- Describe the Common Crawl processing pipeline (8 stages)
- Explain why 99% of raw Common Crawl is discarded
- Evaluate licensing risk for a given data source
- Design a domain-specific data collection pipeline