GPU Evolution & Tensor Cores
From Volta to Blackwell — each GPU generation's key innovations, how Tensor Cores evolved, precision formats, and how to choose the right GPU.
GPU architectures evolve every 2 years, and each generation introduces innovations that reshape AI infrastructure. This chapter traces the evolution from Volta (2017) to Blackwell (2024), focusing on what changed and why it matters for AI workloads.
1. Architecture Evolution Timeline
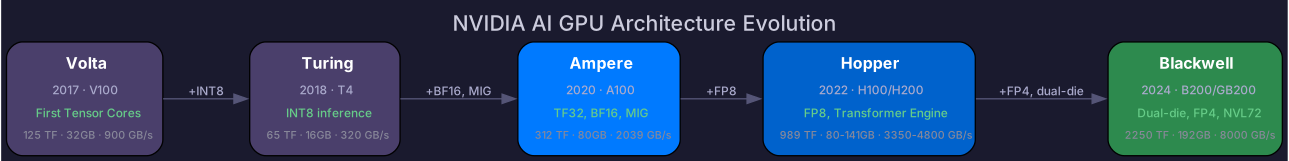
| Year | Architecture | Landmark GPU | Key AI Innovation |
|---|---|---|---|
| 2017 | Volta | V100 | First Tensor Cores (FP16 MMA) |
| 2018 | Turing | T4 | INT8 inference, RT cores |
| 2020 | Ampere | A100 | TF32, BF16, MIG, 3rd-gen Tensor Cores |
| 2022 | Hopper | H100 | FP8, Transformer Engine, NVLink 4.0 |
| 2024 | Blackwell | B200 | Dual-die, FP4, NVLink 5.0 (1.8 TB/s) |
Each generation roughly doubles AI compute while addressing the previous generation’s bottleneck.
2. Volta (2017): The AI Starting Point
Before Volta, deep learning relied on generic CUDA Cores for matrix math. Volta introduced Tensor Cores — purpose-built hardware for matrix multiply-accumulate (MMA).
First-gen Tensor Core: Each cycle completes a mixed-precision MMA — input in FP16, accumulate in FP32. One Tensor Core does in one cycle what takes a CUDA Core ~64 cycles.
V100 Key Specs
| Spec | Value |
|---|---|
| Tensor Cores | 640 |
| FP16 Tensor TFLOPS | 125 |
| FP32 CUDA TFLOPS | 15.7 |
| Memory | 16/32 GB HBM2 |
| Bandwidth | 900 GB/s |
| NVLink | 2.0, 300 GB/s bidirectional |
Legacy: V100 was the first true “AI training card.” Understanding its Tensor Core design is the foundation for understanding every subsequent architecture.
2.5. Turing (2018): Inference Acceleration
Turing is often skipped in AI discussions because it targeted gaming (RT cores for ray tracing). But the T4 — Turing’s data center SKU — remains one of the most widely deployed inference GPUs in the world.
T4 Key Specs
| Spec | Value |
|---|---|
| Tensor Cores | 320 (2nd gen) |
| FP16 Tensor TFLOPS | 65 |
| INT8 Tensor TOPS | 130 |
| Memory | 16 GB GDDR6 |
| Bandwidth | 320 GB/s |
| TDP | 70W |
Why T4 matters: At 70W and $0.50/hour on cloud, T4 is the cheapest way to serve small-to-medium models with INT8 quantization. It’s the “Honda Civic” of inference GPUs — not exciting, but incredibly cost-effective.
Turing’s AI contribution: First Tensor Core support for INT8 inference, enabling 2× throughput vs FP16 for quantized models.
3. Ampere (2020): The Data Center Inflection
Ampere was the generation where AI became the primary data center workload, not a secondary use case.
TF32: Automatic Acceleration
Ampere introduced TF32 (TensorFloat-32) — same 8-bit exponent as FP32 (preserving range) with 10-bit mantissa like FP16 (reducing precision). On A100, when you run torch.matmul on FP32 tensors, the Tensor Cores automatically use TF32 — no code changes needed.
MIG: Multi-Instance GPU
MIG partitions one A100 into up to 7 isolated GPU instances, each with dedicated memory, cache, and compute. This transforms GPU scheduling for inference — multiple small models on one GPU without interference.
# Create two MIG instances
sudo nvidia-smi mig -cgi 9,9 -C
BF16 Support
Ampere added native BF16 Tensor Core support — same dynamic range as FP32, enabling mixed-precision training without loss scaling. This simplified training infrastructure significantly.
A100 Key Specs
| Spec | Value | vs V100 |
|---|---|---|
| Tensor Cores | 432 (3rd gen) | Different MMA shapes |
| FP16/BF16 Tensor TFLOPS | 312 | 2.5× |
| TF32 Tensor TFLOPS | 156 | New |
| Memory | 40/80 GB HBM2e | 2.5× |
| Bandwidth | 2,039 GB/s | 2.3× |
| NVLink | 3.0, 600 GB/s | 2× |
| MIG | Up to 7 instances | New |
4. Hopper (2022): Built for Large Models
Hopper was designed specifically for the large-model era — when models exceeded single-GPU memory and training runs lasted months.
FP8 Training
Fourth-gen Tensor Cores support FP8 in two flavors:
| Format | Exponent | Mantissa | Best for |
|---|---|---|---|
| E4M3 | 4 bits | 3 bits | Forward pass (precision-oriented) |
| E5M2 | 5 bits | 2 bits | Backward pass (range-oriented) |
FP8 doubles Tensor Core throughput vs BF16 — but the reduced precision requires careful management.
Transformer Engine
The Transformer Engine is hardware-software co-design: before each layer’s computation, it analyzes the tensor value distribution and dynamically selects FP8 or BF16. Like an automatic transmission — FP8 on straightaways (numerically stable layers), BF16 on curves (sensitive layers).
import transformer_engine.pytorch as te

# Replace standard Linear with FP8-capable version
model.layer = te.Linear(hidden_size, hidden_size)

with te.fp8_autocast(enabled=True):
    output = model(input_data)
NVLink 4.0 + NVSwitch
| Spec | H100 | vs A100 |
|---|---|---|
| NVLink bandwidth | 900 GB/s bidirectional | 1.5× |
| NVSwitch | Full 8-GPU mesh | All-to-all at full BW |
With 900 GB/s NVLink, intra-node communication is fast enough that tensor parallelism across 8 GPUs adds minimal overhead.
H100 Key Specs
| Spec | Value | vs A100 |
|---|---|---|
| Tensor Cores | 528 (4th gen) | |
| FP16/BF16 TFLOPS | 989 | 3.2× |
| FP8 TFLOPS | 1,979 | New |
| Memory | 80 GB HBM3 | Same capacity, faster |
| Bandwidth | 3,350 GB/s | 1.6× |
| TDP | 700W | 1.75× |
5. Blackwell (2024): The Dual-Die Revolution
Blackwell’s design philosophy: instead of cramming more transistors onto one die, interconnect two dies into a single logical GPU.
Dual-Die Architecture
B200 packages two dies connected via 10 TB/s chip-to-chip interconnect. To software, it appears as one GPU — but has the compute of two. Like coupling two engines to one car: the driver’s interface doesn’t change, but power doubles.
FP4: New Precision Frontier
Fifth-gen Tensor Cores add FP4 — 4-bit floating point for inference. This enables models that previously required 2 GPUs to fit on 1 GPU, doubling inference density.
NVLink 5.0
| Spec | Blackwell | vs Hopper |
|---|---|---|
| NVLink bandwidth | 1,800 GB/s | 2× |
| Connected GPUs | Up to 72 (via NVLink Switch) | 9× |
1.8 TB/s approaches HBM bandwidth — inter-GPU communication is no longer the bottleneck it once was. This fundamentally changes distributed training: communication overhead that required careful optimization can now be absorbed by raw bandwidth.
H200: More Memory, Same Compute
Before Blackwell shipped, NVIDIA released H200 — an H100 with upgraded memory:
- Same Hopper compute (989 TFLOPS FP16)
- 141 GB HBM3e (vs 80 GB HBM3) at 4,800 GB/s
- Targets long-context inference where KV cache is the bottleneck
H200 shows NVIDIA’s strategy: ship memory upgrades between architecture generations to capture the inference market.
GB200 NVL72: The Rack-Scale System
Blackwell’s flagship isn’t a single GPU — it’s GB200 NVL72: 36 Grace CPUs + 72 Blackwell GPUs in a single rack, connected via NVLink 5.0. Total system: 162,000 TFLOPS FP8, 13.5 TB HBM3e. This is a full-rack AI computer, not individual GPUs bolted together.
B200 Key Specs
| Spec | Value | vs H100 |
|---|---|---|
| FP16/BF16 TFLOPS | 2,250 | 2.3× |
| FP8 TFLOPS | 4,500 | 2.3× |
| FP4 TOPS | 9,000 | New |
| Memory | 192 GB HBM3e | 2.4× |
| Bandwidth | 8,000 GB/s | 2.4× |
| TDP | 1,000W | 1.4× |
The Physical Constraints
GPU performance is ultimately limited by physics, not architecture:
| Constraint | Impact | Trend |
|---|---|---|
| Power (TDP) | More compute → more heat. V100: 300W → B200: 1000W. Data centers must provision 3-4× more power per rack for AI vs traditional workloads. | Growing 1.3-1.5× per generation |
| Die size | Larger die → more transistors → more compute. But max reticle size (~814 mm²) limits single-die scaling. Blackwell’s answer: dual-die. | Approaching physical limit |
| Cooling | At 1000W per GPU, 8-GPU nodes consume 8 kW — air cooling maxes out around 25 kW/rack. Modern AI clusters require liquid cooling. | Mandatory for current gen |
| Packaging | HBM is stacked on a silicon interposer next to the GPU die. More HBM stacks → wider interposer → higher manufacturing cost. | CoWoS packaging is a bottleneck |
These constraints explain why Blackwell went dual-die instead of making one bigger die, and why GPU costs keep rising even as transistor density improves.
6. Cross-Generation Comparison
Compute Evolution
| GPU | FP16 TFLOPS | FP8 TFLOPS | Gen-over-gen |
|---|---|---|---|
| V100 | 125 | — | Baseline |
| A100 | 312 | — | 2.5× |
| H100 | 989 | 1,979 | 3.2× / 6.3× |
| B200 | 2,250 | 4,500 | 2.3× |
Memory Evolution
| GPU | Capacity | Bandwidth | Bandwidth/capacity |
|---|---|---|---|
| V100 | 32 GB | 900 GB/s | 28 GB/s per GB |
| A100 | 80 GB | 2,039 GB/s | 25 GB/s per GB |
| H100 | 80 GB | 3,350 GB/s | 42 GB/s per GB |
| H200 | 141 GB | 4,800 GB/s | 34 GB/s per GB |
| B200 | 192 GB | 8,000 GB/s | 42 GB/s per GB |
H200 is essentially H100 compute with more memory — specifically targeting long-context inference where KV cache is the bottleneck.
Key Feature Timeline
| Feature | First introduced |
|---|---|
| Tensor Cores | Volta (2017) |
| INT8 inference | Turing (2018) |
| TF32 | Ampere (2020) |
| BF16 Tensor Cores | Ampere (2020) |
| MIG | Ampere (2020) |
| FP8 Tensor Cores | Hopper (2022) |
| Transformer Engine | Hopper (2022) |
| FP4 Tensor Cores | Blackwell (2024) |
| Dual-die GPU | Blackwell (2024) |
| NVLink 72-GPU mesh | Blackwell (2024) |
7. How to Choose the Right GPU
For Training
| Scenario | Recommended | Why |
|---|---|---|
| Small models (< 10B) | A100 80GB | Best price-performance, mature ecosystem |
| Large models (10B–100B) | H100 SXM | FP8 + NVLink 4.0 for multi-GPU efficiency |
| Frontier models (> 100B) | B200 / GB200 | 192GB memory + 1.8 TB/s NVLink for scale |
For Inference
| Scenario | Recommended | Why |
|---|---|---|
| Low-cost inference | T4 | 70W, INT8, cheapest per-inference |
| Medium LLM (7B–13B) | A100 / L40S | Sufficient memory, good ecosystem |
| Large LLM (70B) | H100 / H200 | FP8 throughput, HBM3 bandwidth |
| Maximum density | B200 | FP4, 192GB fits largest models on fewer GPUs |
The Real Decision: Cost per Token
The “best” GPU is the one that minimizes cost per token at your quality target. A100s may be cheaper per hour but slower — H100s may be more expensive but process more tokens per dollar due to FP8.
Self-Check
- Name the key AI innovation of each GPU generation (Volta → Blackwell)
- Explain what Tensor Cores do and how they evolved across generations
- Explain TF32 and why it “just works” on Ampere
- Explain FP8 E4M3 vs E5M2 and why Hopper uses both
- Explain the Transformer Engine’s dynamic precision selection
- Explain Blackwell’s dual-die architecture and NVLink 5.0
- Choose an appropriate GPU for a given training or inference scenario