Roofline Analysis for Inference
Is this configuration compute-bound or bandwidth-bound, and how close to the theoretical limit?
Roofline analysis tells you how close to optimal your inference configuration is — and whether improving compute or memory bandwidth would help more.
1. The Roofline Model
Performance is limited by whichever ceiling is lower:
Where arithmetic intensity = FLOPs per byte of memory accessed.
| If AI < balance point | Memory-bandwidth-bound | Optimization: reduce bytes (quantization, batching) |
|---|---|---|
| If AI > balance point | Compute-bound | Optimization: reduce FLOPs (pruning, smaller model) |
H100 balance point: FLOP/byte.
2. Inference Workloads on the Roofline
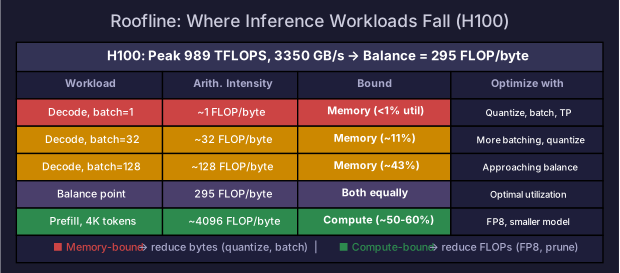
| Workload | Arithmetic intensity | Bound | Why |
|---|---|---|---|
| Decode, batch=1 | ~1 FLOP/byte | Memory | Load all weights for 1 token |
| Decode, batch=32 | ~32 FLOP/byte | Memory | Still below 295 |
| Decode, batch=256 | ~256 FLOP/byte | Memory (borderline) | Approaching balance |
| Prefill, 4K tokens | ~4096 FLOP/byte | Compute | Well above balance |
| Prefill, 128 tokens | ~128 FLOP/byte | Memory | Short prompt, below balance |
Key insight: Decode is almost always memory-bound. Prefill is almost always compute-bound (for reasonable prompt lengths). The optimization strategy differs completely.
3. How to Use Roofline for Configuration Decisions
Should I quantize?
| Configuration | AI | Bound | Quantize? |
|---|---|---|---|
| 70B BF16, batch=8 | 8 | Memory | ✅ INT4 reduces bytes 4× → 4× faster |
| 70B BF16, batch=256 | 256 | Memory (borderline) | ✅ Still helps (moves toward compute-bound) |
| 70B BF16, prefill 4K | 4096 | Compute | ❌ Won’t help (already compute-limited) |
Should I add more TP?
Higher TP splits weights across GPUs → each GPU loads fewer bytes → faster decode:
- TP=4 → each GPU: 35 GB weights → AI still ~1 FLOP/byte → still memory-bound but 4× less data per GPU
Should I batch more?
More batching → higher AI → closer to compute utilization:
- But requires more KV cache memory → limits max batch size
4. Measuring Actual Utilization
| Configuration | Expected MFU | Why |
|---|---|---|
| Decode, batch=1 | <1% | Massively memory-bound |
| Decode, batch=32 | ~10% | Better but still memory-bound |
| Prefill, 4K tokens | 40-60% | Compute-utilized |
| Prefill + decode mixed | 20-40% | Depends on mix |
For the prefill/decode arithmetic intensity derivation, see Prefill & Decode Phases.
Self-Check
- Calculate arithmetic intensity for decode at batch=1 and batch=64
- Determine if a given configuration is compute-bound or memory-bound
- Predict whether quantization or batching would help more
- Calculate MFU for a given throughput and hardware