Prefill & Decode Phases
Compute-bound prefill vs memory-bandwidth-bound decode — the two-phase lifecycle of every request and why decode is the bottleneck.
Every LLM inference request has two phases with fundamentally different computational characteristics. Understanding this split is the key to understanding every inference optimization technique.
1. The Two Phases
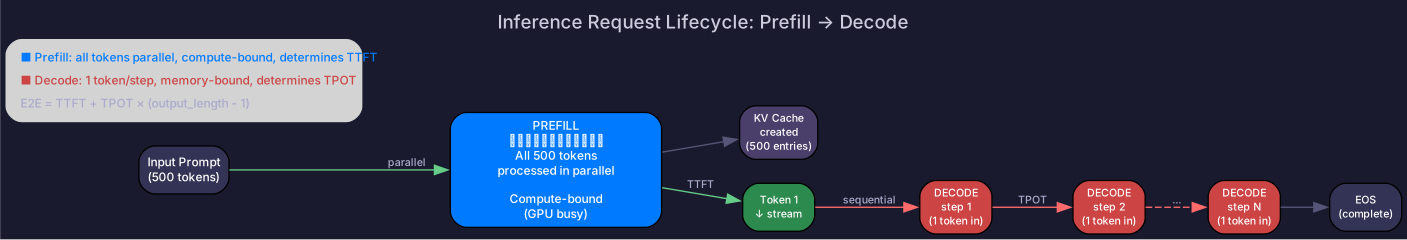
Prefill (Prompt Processing)
The entire input prompt is processed in parallel — all tokens go through the model simultaneously in one forward pass. This produces the KV cache for all input tokens and generates the first output token.
- Input: Full prompt (tens to thousands of tokens)
- Parallelism: High — all tokens processed simultaneously
- Bottleneck: Compute-bound (large matrix multiplications)
- Output: KV cache + first token
- Determines: TTFT (Time To First Token)
Decode (Token Generation)
Starting from the second output token, the model generates one token per step. Each step takes the single previously generated token as input, runs a full forward pass, and produces the next token.
- Input: 1 token per step
- Parallelism: Low — sequential across steps
- Bottleneck: Memory-bandwidth-bound (entire model weights loaded for 1 token)
- Output: 1 token per step
- Determines: TPOT (Time Per Output Token)
Side-by-Side Comparison
| Dimension | Prefill | Decode |
|---|---|---|
| Input tokens per step | Entire prompt (100-100K) | 1 token |
| Parallelism | High (tokens are parallel) | Low (steps are sequential) |
| Bottleneck | Compute-bound | Memory-bandwidth-bound |
| Key metric | TTFT | TPOT |
| Executions per request | 1 time | Output length - 1 times |
| GPU compute utilization | High (50-80%) | Low (<5% for single request) |
2. Why Decode Is Memory-Bound
This is the most counterintuitive fact in LLM inference: generating a single token requires loading the entire model from HBM, but performs very little computation.
The Arithmetic Intensity Argument
For a single decode step, the core operation is “weight matrix × single-token vector” for every layer. Consider a model with bytes of weights (BF16):
- Memory traffic: Load all bytes of weights from HBM (each weight read once)
- Computation: Each of the weights (2 bytes each) participates in one multiply-add = 2 FLOPs. Total: FLOPs
- Arithmetic intensity: ratio of compute to memory traffic
Now compare to H100’s balance point — where compute and memory bandwidth are equally saturated:
Single-request decode has arithmetic intensity 1 — that’s 295× below the H100’s balance point. The GPU’s compute units sit idle ~99% of the time, waiting for weights to arrive from memory.
Key insight (from AIInfraGuide): Decode is slow not because of insufficient compute, but because the GPU must load the entire model’s weights from HBM just to produce one token. The weights-to-useful-work ratio is devastating.
Why Prefill Is Compute-Bound
The mirror argument: during prefill, all prompt tokens share the same weight load:
For a 4K prompt: arithmetic intensity = 4096 — well above H100’s 295 balance point. The GPU’s compute units are fully utilized; memory bandwidth is not the bottleneck.
Batching: The Primary Solution
Batching requests together changes the arithmetic intensity:
Weights are loaded once but serve requests. To reach H100’s balance point: .
This is why batching barely increases per-request latency but dramatically increases throughput — it’s utilizing compute that was previously idle.
This arithmetic intensity analysis is the “X-ray” for understanding all inference optimizations. Weight-only quantization works because it reduces (bytes to move). Batching works because it increases (work per byte moved).
3. KV Cache: What Changes Between Steps
During prefill, the model computes K and V projections for every input token at every layer. These are stored as the KV cache — the model’s “memory” of previous tokens.
During each decode step:
- Compute Q, K, V for the new token only
- Append new K, V to the existing KV cache
- Attend to all cached K, V (growing with each step)
- The rest of the forward pass (FFN, etc.) processes only the new token
Decode step t:
  New token → Q_new, K_new, V_new
  KV cache: [K_1..K_{t-1}, K_new], [V_1..V_{t-1}, V_new]
  Attention: Q_new × [K_1..K_t]^T → weights → × [V_1..V_t] → output
  FFN: processes only the new token's hidden state
The KV cache grows by one token’s worth per step — memory consumption increases throughout generation.
For detailed KV cache memory analysis, see KV Cache.
4. The Full Inference Pipeline
A complete request flows through:
Request arrives
  │
  ├── Queue: wait for scheduler to assign GPU resources
  │
  ├── Prefill: process entire prompt in parallel
  │     └── Output: KV cache + first token → stream to user
  │
  ├── Decode step 1: generate token 2
  │     └── Output: token 2 → stream to user
  │
  ├── Decode step 2: generate token 3
  │     └── ... (repeat until EOS or max length)
  │
  └── Complete: release KV cache memory
End-to-end latency:
Note: TTFT already includes queue wait time and prefill compute. For debugging, you can decompose: .
For short outputs, TTFT dominates. For long outputs, TPOT dominates:
| Scenario | TTFT=500ms, TPOT=40ms | Dominant factor |
|---|---|---|
| 20 tokens output | ms | TTFT (40%) |
| 200 tokens output | ms | TPOT (94%) |
| 800 tokens output | ms | TPOT (98%) |
Optimize TTFT for chatbots (user perceives responsiveness). Optimize TPOT for long generation (code, articles).
5. Implications for Infrastructure
The two-phase nature drives every major inference optimization:
| Optimization | Which phase it targets | How it helps |
|---|---|---|
| Batching | Decode | Increases arithmetic intensity by sharing weight reads |
| KV cache management (PagedAttention) | Decode | More concurrent requests in limited memory |
| Quantization (INT4/FP8) | Both | Fewer bytes to move → faster weight loading |
| Speculative decoding | Decode | Multiple tokens per step |
| Chunked prefill | Prefill | Prevents long prompts from blocking decode |
| PD disaggregation | Both | Separate hardware optimized for each phase |
| Tensor parallelism | Both | Split weights across GPUs for faster loading |
For how modern engines implement these optimizations, see Engine Internals.
Self-Check
- Explain prefill vs decode: input size, bottleneck, key metric
- Calculate arithmetic intensity for single-request decode on H100
- Explain why batching increases throughput without proportional latency increase
- Calculate E2E latency for a given TTFT, TPOT, and output length
- Determine whether to optimize TTFT or TPOT for a given workload
- Map each inference optimization to the phase it targets